Diani Cortex Engine
A production-grade, local-first, human-in-the-loop AI operations runtime engineered to run on constrained 8GB edge machines. Featuring the OmniRoute gateway (Port 20128), 4-bit GGUF quantization, and zero-recurring cloud LLM API bills.
Engineered for Severe Hardware Constraints
How Diani Cortex Engine avoids swap-file thrashing and executes autonomous operations on a dual-core edge laptop.
OmniRoute Gateway & Dual Models
Rather than forcing a single bloated LLM into RAM, the lightweight omniroute.py proxy splits incoming tasks between two 4-bit quantized GGUF models: Hermes for structured English B2B drafting, and a Sheng-Tuned Qwen 2.5 for natural coastal Kenyan client support.
Strict Subprocess Isolation
Heavy workers (youtube_agent.py, linkedin_agent.py, email_agent.py) spawn strictly as isolated child processes via asyncio.create_subprocess_exec. The operating system instantly reclaims their RAM footprint the second a task exits.
Mobile Human-in-the-Loop
Background agents proactively brainstorm angles and stage drafts into hitl_queue.db. A single tap on Telegram approves full production: generating local TTS audio, rendering 9:16 vertical video with FFmpeg, and publishing to YouTube in under 60 seconds.
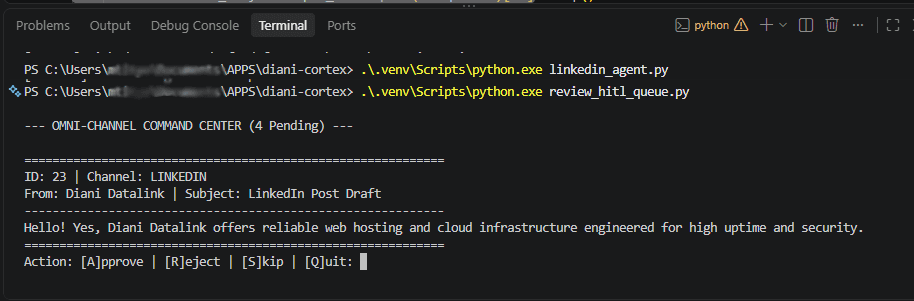
Local-First Staging Queue
Terminal-based Human-In-The-Loop (HITL) staging queue reviewing and approving AI-generated drafts safely offline before mobile deployment.
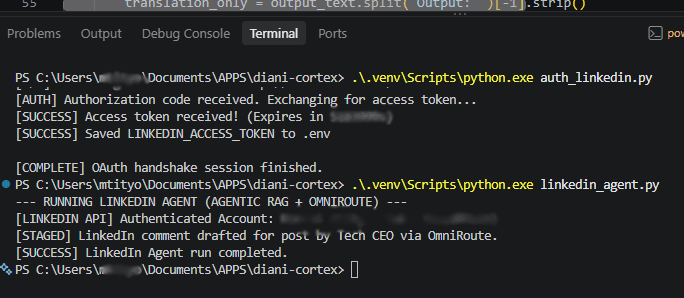
Secure Local API Integration
Background B2B agent executing an OAuth handshake, retrieving a temporary access token, and staging generated drafts via the OmniRoute gateway.