Edge-AI LoRA Pipeline
Adapting Qwen 2.5 for Kenyan Sheng through Low-Rank Adaptation (LoRA), FP16 adapter fusion, and 4-bit GGUF quantization. Engineered to eliminate tokenization fertility bottlenecks and run on 4GB VRAM / 8GB RAM host machines with a minimal 476.2 MB RAM footprint.
Overcoming Dialect & Compute Boundaries
How custom instruction tuning and quantization retain linguistic nuances without burning cloud compute.
Tokenization Fertility
Standard LLM tokenizers fragment urban Sheng terms ("msee", "rada", "tusetup") into multiple subwords, driving up CPU decoding cycles. Targeted instruction tuning teaches the model clean sequential transitions across subwords.
Pragmatic Equivalence
Curated custom JSONL instruction sets reflecting genuine Kenyan tech sales. Technical terms ("hosting", "domain", "package") remain in English while conversational framing shifts fluidly into coastal Sheng.
PEFT / LoRA Attention
Base Qwen 2.5 weights stay completely frozen. Low-rank trainable matrices are injected into attention layers via LLaMA-Factory, preventing catastrophic forgetting and overfitting on localized datasets.
4-Bit GGUF Quantization
Merged FP16 adapters converted via llama.cpp into 4-bit GGUF format. Verified against recurring customer prompts to confirm zero linguistic degradation while leaving 3GB+ free RAM headroom on the host.
Empirical Pipeline Telemetry & Proof
Hardware-verified telemetry confirming sub-second latency and zero swap thrashing.
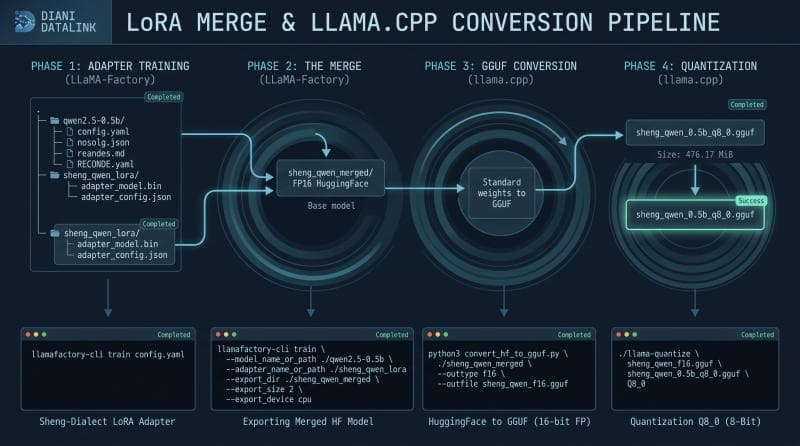
LoRA Training & Export Pipeline
Step-by-step workflow from LLaMA-Factory training, FP16 adapter merge, GGUF export, to llama.cpp deployment.
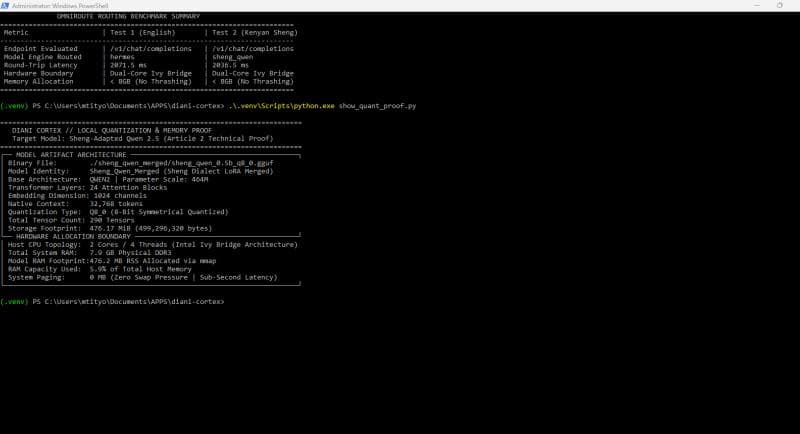
Hardware Memory Telemetry
Real-time terminal telemetry confirming a total RAM consumption of just 476.2 MB on dual-core Ivy Bridge hardware.
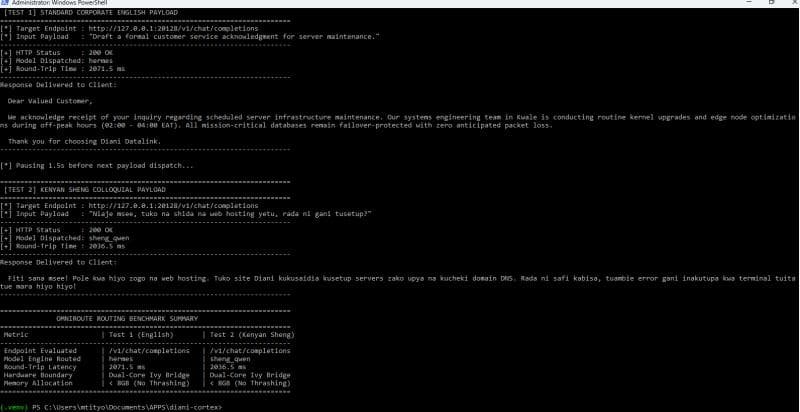
Empirical Benchmark Validation
Benchmarking inference response times, dialect fluency, and memory ceiling limits across quantization variants.
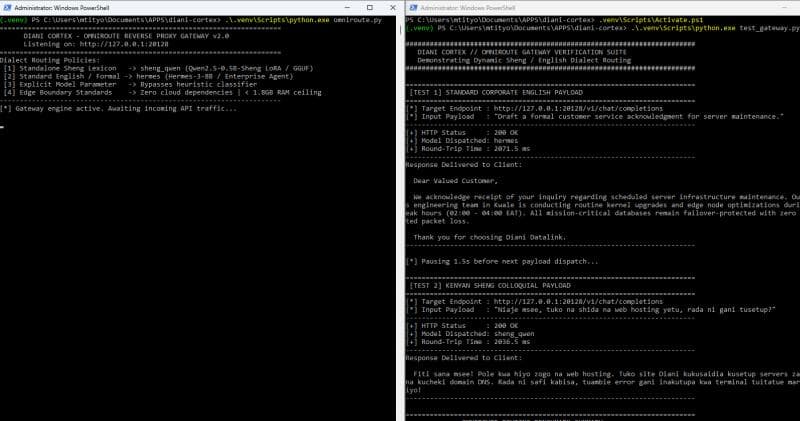
Live OmniRoute Dialect Interception
Dynamic payload routing: English queries dispatch to Hermes; Sheng tokens route directly to the Sheng Qwen model.